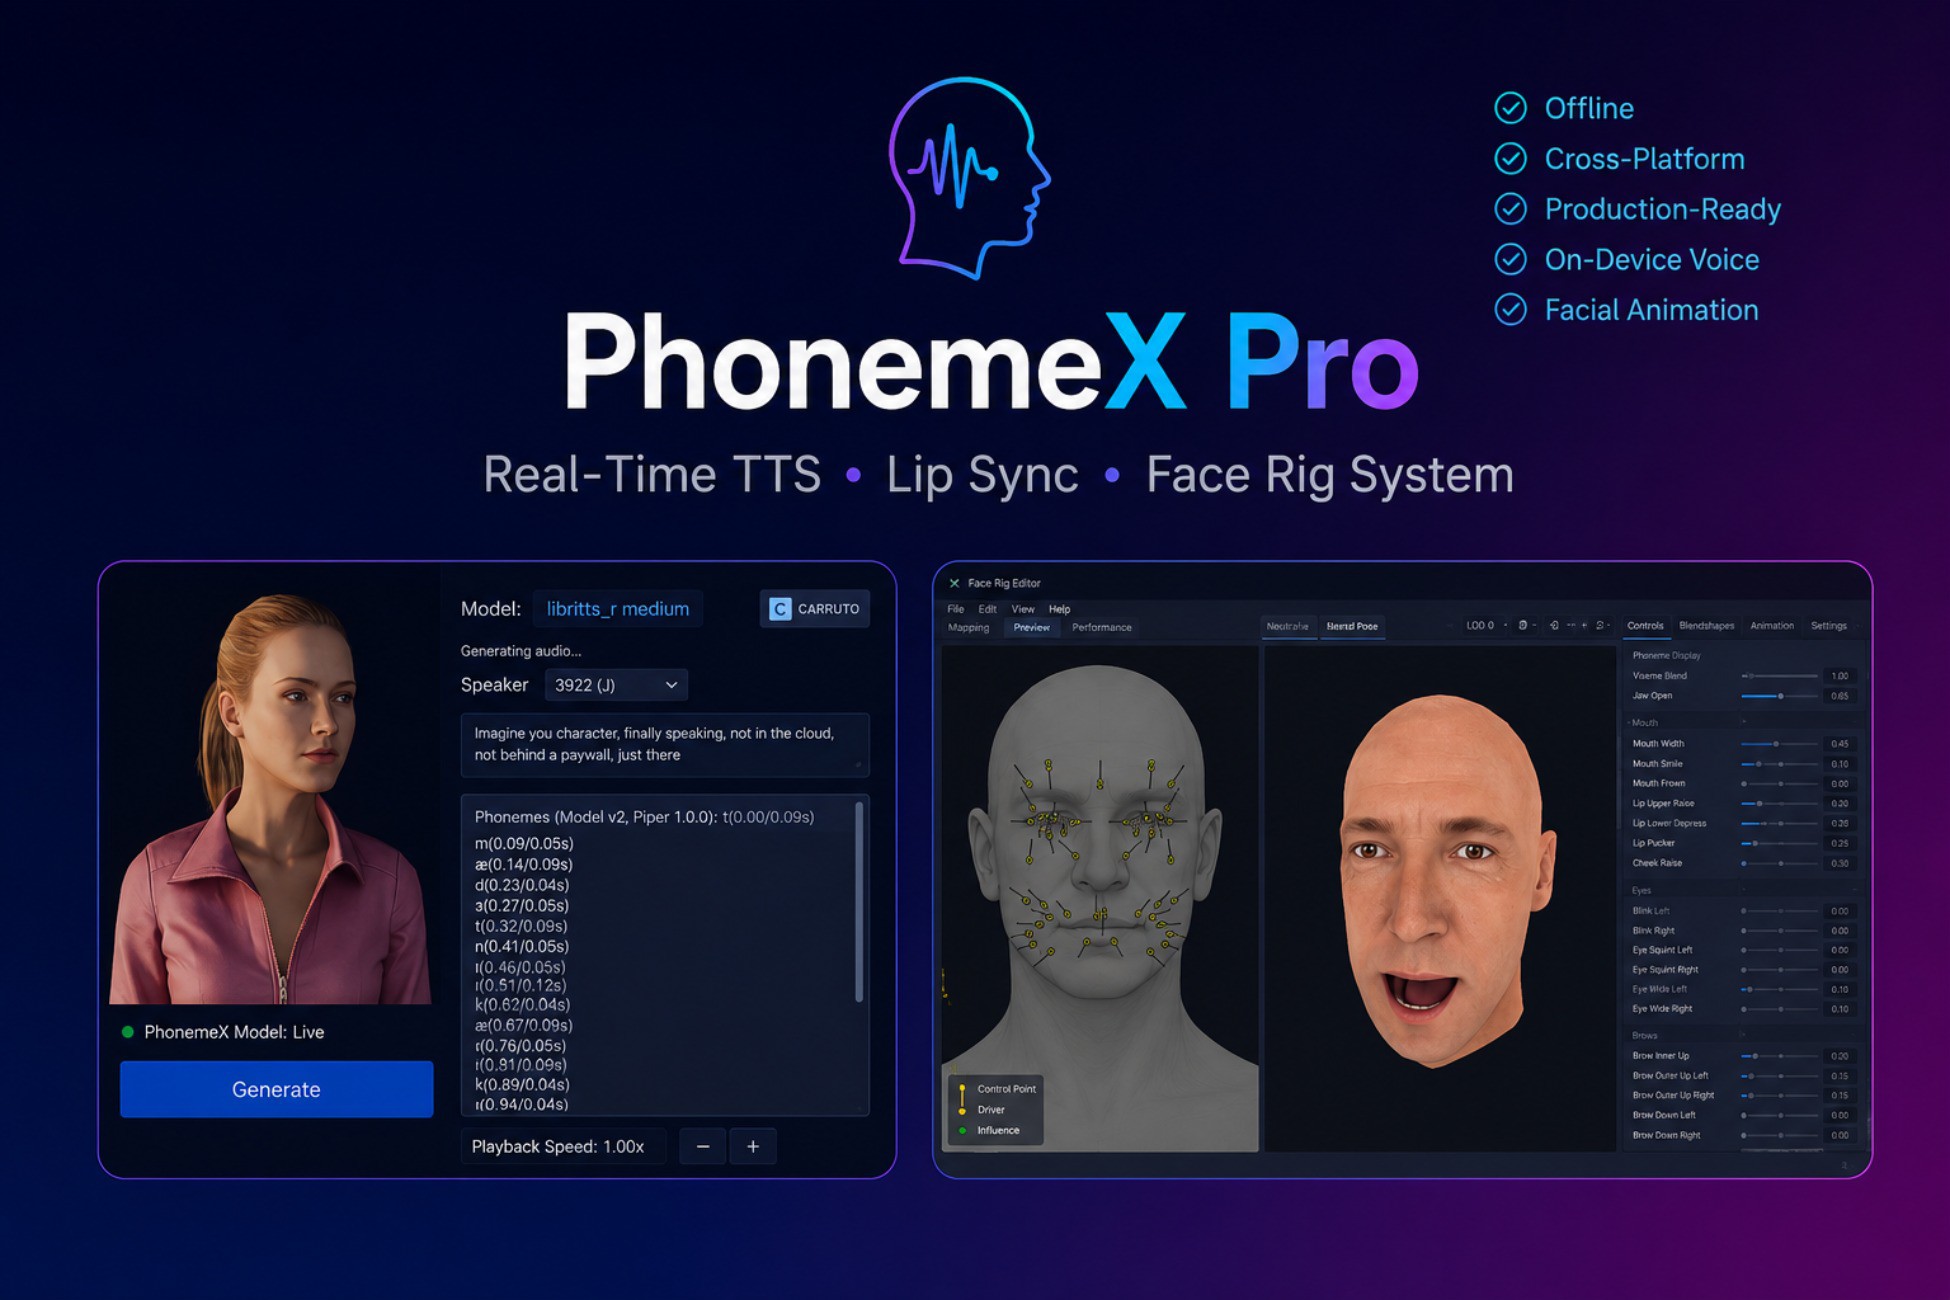
PhonemeX Pro Edition is a modular, fully offline Text-to-Speech, Speech Recognition, and character voice system built for Unity mobile, desktop, and web builds.
It provides real-time, on-device speech synthesis, local speech-to-text transcription, and full access to phoneme timing data at runtime, enabling speech generation, lip-sync, facial animation, and voice-driven character systems.
What’s New in Version 1.2.0
PhonemeX Pro has evolved into a complete bidirectional voice suite. Version 1.2.0 introduces a brand-new Speech Recognition (ASR) module powered by local Whisper models, and a zero-latency Audio-Reactive Lip-Sync system for fast, FFT-based mouth movements. The entire codebase has also been deeply modularized, separating Expressions from Lip-Sync to allow for perfectly layered facial animation without conflicts. Existing projects remain fully compatible.
Core Systems Included
- On-Device Text-to-Speech System
A cross-platform, fully offline TTS engine that runs entirely inside Unity. Generates real-time audio along with detailed phoneme timing data for runtime logic and animation.
- On-Device Speech Recognition System (New!)
A robust ASR pipeline integrating multilingual Whisper models for native speech-to-text inference. Runs completely locally via Unity Sentis (Desktop/Mobile) and WebAssembly (WebGL). Includes a built-in Download Manager UI for easy model fetching.
- Real-Time Lip-Sync System
A dedicated lip-sync pipeline that schedules phoneme data, blends viseme weights, and drives facial motion in real time. Designed for accurate speech-to-animation synchronization.
- Audio-Reactive Lip-Sync (New!)
A high-speed, zero-latency alternative to phoneme lip-sync. Uses real-time FFT band analysis, Automatic Gain Control (AGC), and direct jaw bone rotation for instant audio-driven mouth movement directly from an audio source.
- Modular Avatar System
PhonemeX Pro includes a flexible avatar integration layer compatible with the AvatarX character set. The avatar system applies lip-sync and expression data to fully rigged characters using blendshapes or custom drivers, enabling speech-driven facial animation with minimal setup.
The system is designed to work with a wide range of humanoid characters and animation setups, allowing developers to integrate PhonemeX into existing projects without being locked to a specific character format.
- Face Rig & Expression System
An optional facial rigging and expression framework for authoring, blending, and layering facial poses, emotions, and micro-expressions on top of lip-sync animation.
Modular Design
- Each system can be used independently depending on your project needs:
- Use only the TTS system for speech playback
- Combine TTS and lip-sync for talking characters
- Integrate the avatar and face rig systems for full facial animation control
Modules are loosely coupled and designed to be extended or replaced as your project grows.
Key Features
- Fully Offline, On-Device TTS – No internet connection or server required by default
- Real-Time Phoneme Access – Phoneme timing data available at runtime
- Cross-Platform Support – Android, iOS, WebGL, Windows, macOS, and Linux
- Lightweight & Fast – Optimized for mobile and browser-based builds
- Multi-Voice & Multi-Language ASR Support – Easily switch between models
- Multi-Voice Support – Easily switch between supported voice models
- Modular Runtime Architecture – Clean separation between voice, lip-sync, and animation systems
- Optional online phoneme services can be integrated if desired, but are not required for core functionality.
- Local AI Inference – Uses Unity’s official on-device AI inference packages
- Demo Scenes Included – Examples showcasing TTS, lip-sync, avatar integration, and face rig workflows
Supported Platforms
- Android (ARM / ARM64)
- iOS / iPadOS
- WebGL
- Windows (x86 / x64)
- macOS
- Linux
Dependencies / Requirements
- Unity 6 LTS or newer
- On-device AI inference package: Unity AI
Description sourced from the Unity Asset Store listing.